● DATA & ML ENGINEERING

RAG and MLOps: from “it ran” to reliable production.

We own the entire ML lifecycle — from ingestion through deployment and operations.

100s
GPU orchestration
on-device
deployment
24/7
monitoring
● THE PROBLEM

If this sounds familiar.

If even one of these is familiar, this service closes that gap.

  • The notebook trap

    The model works, but serving, scaling, and cost don't.

  • GPU waste

    Expensive cards sit idle without scheduling.

  • Edge constraints

    You need to move on-device, but conversion·optimization is daunting.

● SCOPE

What, how far, what we leave behind.

We lift models into production services, owning the ML lifecycle from ingestion to operations.

How far

  • Data pipelines
  • Model serving·deployment
  • GPU orchestration·scheduling
  • On-device·edge ML
  • Monitoring·optimization

Deliverables

  • Data·ML pipelines
  • Deployed endpoints or on-device builds
  • GPU operations framework
  • Performance·cost report
● HOW WE WORK

How we work.

  1. PipelineData ingestion·cleaning·features
  2. ServingEndpoints or on-device builds
  3. SchedulingGPU allocation·autoscaling
  4. OperateMonitoring·drift·cost optimization
● EVIDENCE — NOT COPY

A record of what we shipped.

On-device ML · edge inference
on-device
inference
Core ML/ONNX
conversion
0$0
edge server cost

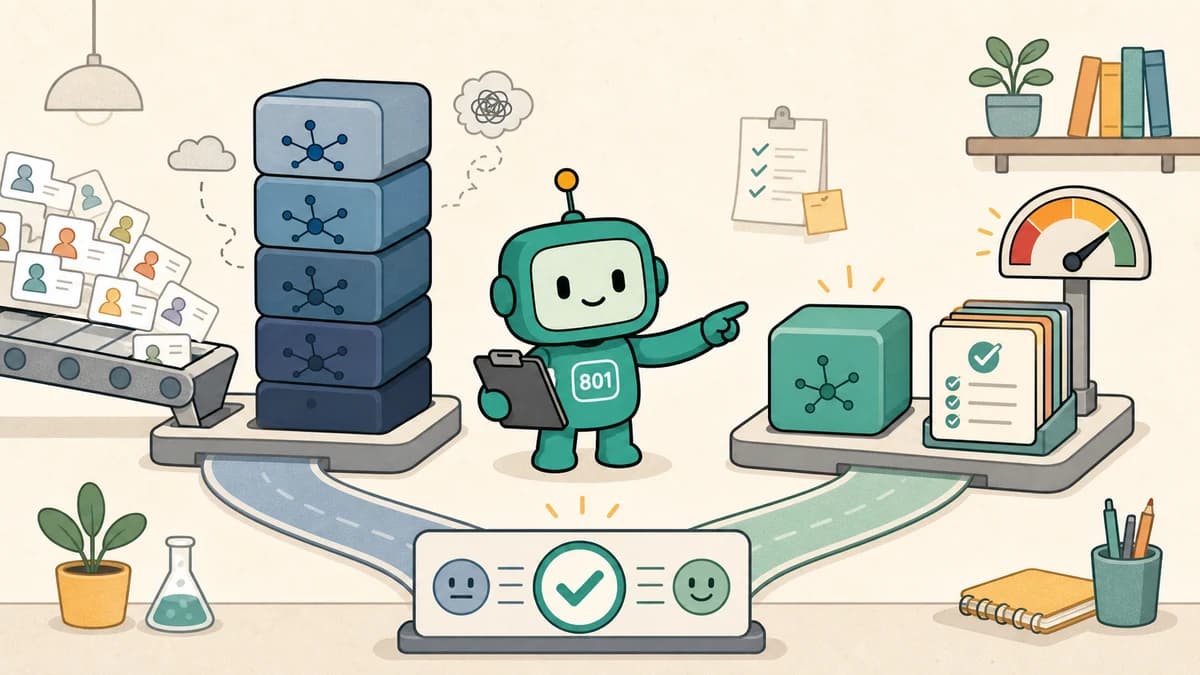
PyTorch models inferring on-device — server cost eliminated.

We exported PyTorch models to Core ML·ONNX for on-device inference, removing server round-trips and their cost.

View case →
● RELATED INSIGHTS

Go deeper from assessment to cutover.

Got models but no ops? We start there.

Request a technical review →
● STACK & DOMAIN

Stack & domain.

PyTorchONNXCore MLTritonKueueSageMakerRay

A team that has handled large-scale GPU operations and edge constraints at the same time.

● FAQ

Frequently asked.

We have the model — can you just deploy it?+
Yes. Serving·scheduling is our most common standalone request.
Can you take it from data collection?+
Yes. We own the whole ML lifecycle — from ingestion, cleaning, and features through serving and operations.
What if quality drifts after deployment?+
We add monitoring and drift detection to track performance and cost, and pin down when to retrain.
Does on-device really cut cost?+
The more inference traffic, the more server cost disappears — the bigger the win.
Our GPU cost is out of control.+
Scheduling, autoscaling, and visibility raise utilization and throughput per card.

Take your model to production.

We review the environment and challenge first, then define the right execution scope together.

● Already trusted by teams across finance · healthcare · media · public
Request a technical review →